How to Build an AI Agent Automation Workflow in 5 Minutes: From Initialization to a Complete Inspection Loop
Stop writing repetitive prompts and start designing self-driving loops. This step-by-step tutorial shows you how to use the open-source loop-engineering CLI to initialize daily triage patterns, audit Loop readiness, estimate token costs, and build a reusable, auditable AI Agent workflow for any project.
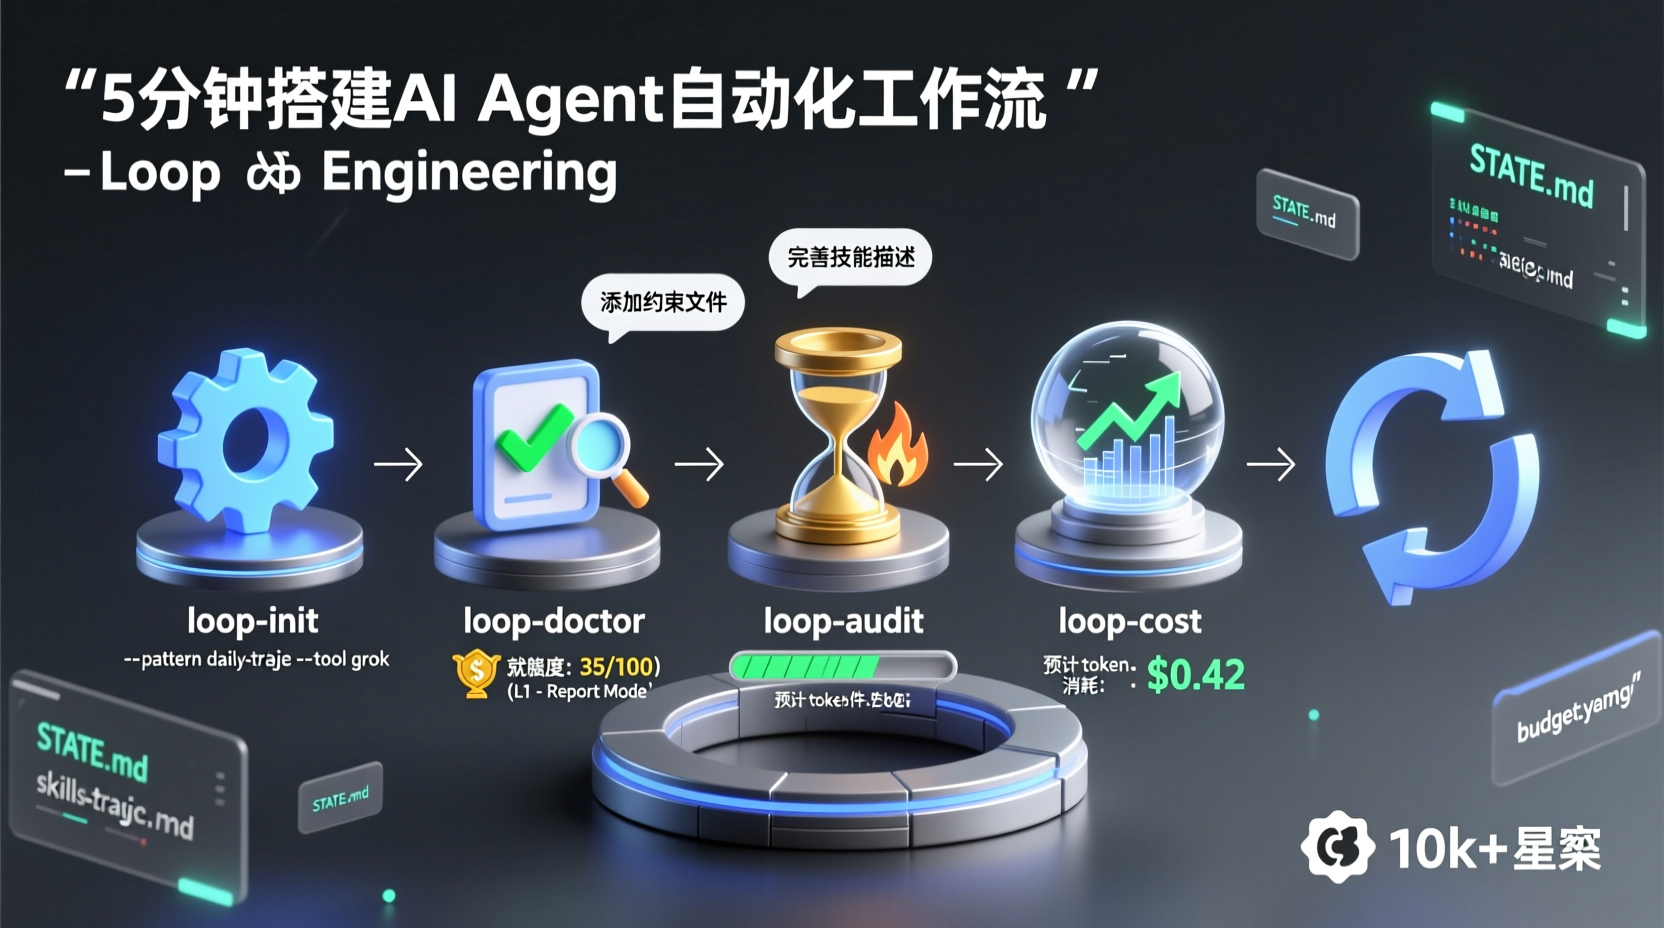
Stop Writing Prompts. Design Loops That Run Your Agents: A Practical Guide to AI Agent Automation Workflows
After years of Java backend development, I’ve realized something fundamental: writing prompts for AI coding tools is essentially the same as writing shell scripts. No matter how detailed you make them, they execute once and then stop. Next time, you’re back at square one, rewriting everything.
That changed when I discovered Loop Engineering (10k+ stars on GitHub). Its core philosophy is straightforward:
"You shouldn't be prompting coding agents anymore. You should be designing loops that prompt your agents."
In plain English: Instead of manually telling an AI what to do every time, design an automated loop system that drives the AI for you.
Boris Cherny, head of Claude Code, put it similarly: "I no longer write prompts for Claude. My job is to write loops."
In this tutorial, I’ll walk you through building a complete AI Agent automated inspection workflow from scratch in just 5 minutes using the loop-engineering CLI toolchain. By the end, you’ll have a reusable Loop template ready to drop into your own team’s projects.
Prerequisites
Before we begin, ensure you meet the following requirements:
| Requirement | Description |
|---|---|
| Node.js ≥ 18 | Distributed via npx, no global installation needed |
| Git Repository | You need an existing Git project to run this in |
| AI Coding Tool | Supports Grok, Claude Code, Codex, OpenCode, or similar |
| npm with Internet Access | Initial npx run will fetch packages from npm |
If you don’t have a suitable project locally, you can quickly create an empty one:
mkdir my-loop-demo && cd my-loop-demo && git init
Step 1: Initialize the Project Template with loop init
This is the most critical step. loop init generates three core files for you: Skills (capability definitions), State (persistent memory), and Budget (token limits), then automatically calculates a Loop Ready Score. This score tells you which maturity level your current Loop sits at (L1, L2, or L3).
Open your terminal, navigate to your project’s root directory, and run:
bash
npx @cobusgreyling/loop init . --pattern daily-triage --tool grokLet’s break down the arguments:
--pattern daily-triage: Specifies the "Daily Inspection" pattern. It’s the most beginner-friendly of the 7 presets: low token consumption, report-only in week one, and maximizes safety.--tool grok: Specifies your AI tool. You can swap this forclaude,codex,opencode, etc.
After running, you’ll see output similar to this:
✓ Created STATE.md
✓ Created skills/triage.md
✓ Created budget.yaml
🏆 Loop Ready Score: 35/100 (L1 - Report Mode)
→ Next: run "npx @cobusgreyling/loop doctor ." for top 3 actions
Why is the score only 35? Perfectly normal. A fresh project scores low initially because it lacks complete constraint files and execution logs. That’s exactly what the next step addresses.
Why not create these files manually? Skills files define what the Agent does in a Loop (e.g., checking issues, reading logs, writing reports). State files maintain cross-conversation memory. Budget files cap token usage. The project enforces strict structural conventions for these files. A single typo manually can cause unpredictable Agent behavior.
Step 2: Run a Health Check with loop doctor
loop doctor is the unified diagnostic command for the CLI. It bundles audit, sync check, and file validation into a single command that tells you exactly: "Here are the top 3 things you should do right now."
bash
npx @cobusgreyling/loop doctor .Example output:
📋 Top 3 recommended actions:
1. Add constraints file (.loop/constraints.yaml) → +15 points
2. Create run-log.json for execution history → +10 points
3. Verify STATE.md syntax → +5 points
Current Score: 35/100 → Projected: 65/100 (L1)
Why run doctor before diving in? The recommendations are prioritized based on thousands of real-world Loop runs by the project authors. Following their advice guarantees linear score improvements. Guessing on your own often wastes time on low-impact tasks.
Step 3: Hands-On — Running the Daily Triage Loop End-to-End
With the foundation in place, let’s walk through a complete Daily Triage cycle.
3.1 Estimate Costs First
Before letting the Agent run wild, use loop-cost to estimate token consumption and avoid budget blowouts:
bash
npx @cobusgreyling/loop cost --pattern daily-triage --level L1You’ll see token estimates per phase. L1 mode (report-only) typically consumes a few hundred to a few thousand tokens per day—very low. If you plan to upgrade to L2 (assistive fixing), costs will spike significantly. This is precisely why the authors recommend sticking with L1 for your first week.
3.2 Launch Your First Inspection
After initialization, loop init prints a recommended starting command. If you’re using Grok, it looks roughly like this:
text
/loop 1d Run loop-triage. Update STATE.md. No auto-fix in week one.What this means:
/loop 1d: Run in Loop mode with a 1-day cycleRun loop-triage: Execute the inspectionUpdate STATE.md: Write results back to the state fileNo auto-fix in week one: Report-only during week one; do not auto-modify code
Safety Note: The tool’s security philosophy is highly conservative. In L1, the Agent has no write permissions to your code. It only reads and reports. This aligns with a seasoned backend developer’s mindset: "Observe first, refactor later." Never let a machine touch your core code blindly on day one.
3.3 Check Execution Status
Once the inspection finishes, check the current status:
bash
npx @cobusgreyling/loop status .This displays a summary of STATE.md, the latest run log, and your current score. You’ll watch the score climb steadily with each run: 35 → 65 → 80+, tracking your progression from L1 (Report) → L2 (Assist) → L3 (Unattended).
Core Patterns Overview
loop-engineering ships with 7 production-ready Loop patterns, each with preset cycles, starter templates, and token cost estimates:
| Pattern | Cycle | Week One Behavior | Token Cost |
|---|---|---|---|
| Daily Triage (Used today) | 1 day ~ 2 hours | L1 Report Only | Low |
| PR Babysitter | 5 ~ 15 min | L1 Monitoring | High |
| CI Sweeper | 5 ~ 15 min | L2 Cautious Fix | Very High |
| Dependency Sweeper | 6 hours ~ 1 day | L2 Patches Only | Medium |
| Changelog Drafter | 1 day or per tag | L1 Draft Only | Low |
| Post-Merge Cleanup | 1 day ~ 6 hours | L1 Off-Peak Exec | Low |
| Issue Triage | 2 hours ~ 1 day | L1 Suggestions Only | Low |
Unsure which to pick? Run loop-init without the --pattern flag, and the CLI will guide you interactively.
Pitfalls to Avoid
Based on my hands-on experience and community feedback, here are common traps to watch out for:
- Windows Path Issues: The project has known CRLF-related bugs on Windows (Issue #483). Use WSL or Git Bash to avoid newline parsing failures.
- Never Enable Auto-Fix in L1: The authors repeatedly stress that L1 is an observation phase. The Agent doesn’t know your codebase yet; auto-fixing can introduce subtle bugs.
- Token Costs Will Explode If Rushed: Jumping straight to L3 (fully unattended) with sub-agent splitting can multiply token usage by 10x to 50x compared to L1. Always run
loop-costfirst. - Understand "Comprehension Debt": The project introduces a crucial concept: if you don’t review Agent-submitted code line-by-line, debt compounds rapidly. Loops don’t understand code for you; they just save you time. You remain the engineer accountable for the codebase.
- Same Loop, Different Results: Execution quality hinges on your
STATE.mdand Skills files. Two engineers using the same pattern will get wildly different outcomes if one writes detailed instructions and the other leaves them vague.
Summary & Next Steps
We’ve just walked through the complete workflow:
loop init→ Initialize templates & get your Loop Ready Scoreloop doctor→ Get Top 3 prioritized improvementsloop cost→ Estimate token consumption- Run L1 Inspection → Agent reports only, no modifications
loop status→ Review execution results
In under 10 minutes, your project now has an iterative, auditable, and upgradeable AI Agent workflow framework.
Recommended Next Steps:
- Once your
Loop Ready Scorehits 80+, consider adding--with-foundryto version your Loops into a composable runtime stack (Harness Runtime). - Want to integrate Loops into CI? Check out
loop-action(GitHub Actions integration). - Managing multiple Agents across teams? Explore the sibling projects
fleet-engineeringandmemory-engineeringfor cross-Agent memory and governance.
To close with Addy Osmani’s words: "Build the loop. But build it like someone who intends to stay the engineer, not just the person who presses go."
Design your loops, but build them with the mindset that you remain the engineer responsible for the system—not just someone hitting the start button.
Project: cobusgreyling/loop-engineering | Docs: Interactive Showcase